Headquarters
13th Floor, GIFT Tower One, GIFT City, Gandhinagar, GujaratMVP → PRODUCTION CONSULTING
Home / Consulting / MVP to Production
MVP → Production Consulting
The hardest gap in AI. Your demo works; your production system doesn't. We help teams move AI prototypes and early MVPs into reliable production systems by solving the challenges that usually appear after the demo: reliability, evaluation, cost, latency, security, deployment, and monitoring.
Advisory Overview
Typical Engagement: 2 to 6 Weeks AdvisoryAI prototypes can perform well in controlled demos but break down when real users, production traffic, larger datasets, and enterprise requirements are introduced. Our consultants identify and address the technical gaps between an AI prototype and a production-ready system — from model evaluation and reliability to infrastructure, performance, security, and operational monitoring.
Tangible Deliverables You Receive
- Production Readiness Assessment and Gap Analysis
- AI Evaluation Framework and Reliability Benchmarks
- Cost & Latency Optimization Plan
- Production Deployment Architecture
- Security, Monitoring & Observability Blueprint
Framework
Our 4-Step Advisory Process
How our senior technology consultants guide your team from initial audit to production handover.
Step 01
Production Readiness Audit
We evaluate your AI application architecture, model integrations, prompts, data pipelines, APIs, cloud infrastructure, security controls, secrets management, and failure handling to identify production-critical gaps.
Step 02
Evaluation & Reliability Testing
We establish evaluation criteria, test datasets, quality benchmarks, regression tests, and failure scenarios to measure AI output quality and system reliability before production deployment.
Step 03
Cost & Latency Optimization
We analyze model selection, token usage, inference patterns, API calls, database queries, caching, and infrastructure utilization to reduce operating costs and improve response times.
Step 04
Production Deployment & Monitoring
We design the production deployment architecture and establish CI/CD, logging, tracing, monitoring, alerting, and incident-response processes required to operate the AI system reliably at scale.
Technologies & Supported Stacks
OpenAI / Anthropic / GeminiLangChain / LangGraphPython / FastAPI / Node.jsAWS / GCP / AzureDocker / KubernetesTerraform / OpenTofuPostgreSQL / RedisGitHub Actions / GitLab CIDatadog / Prometheus / GrafanaSentry / OpenTelemetry
Business Impact
- Reliable AI systems that perform beyond controlled demos
- Measurable AI quality with structured evaluation and testing
- Lower model, API, and infrastructure costs
- Faster and more predictable response times
- Secure production deployments with proper monitoring
- A scalable technical foundation for growing AI workloads
Common Scenarios
- Transitioning an AI prototype or MVP into production
- Preparing an AI product for real customer traffic
- Reducing unexpectedly high model and infrastructure costs
- Improving inconsistent AI outputs through systematic evaluation
- Fixing latency, reliability, and scalability issues before launch
- Preparing an AI application for enterprise security and operational requirements
TRANSPARENT ENGAGEMENT FORMATS
Engagement Formats & Pricing
Choose the advisory structure that matches your current momentum. Fixed scopes, transparent pricing, and zero open-ended billing meters.
Fastest Kickoff 1 to 2 Days Intensive
Executive Workshop
$3,500 / ₹2.5L
Fixed All-Inclusive Investment
Leadership alignment, feasibility scoring, and high-level architecture roadmap before committing team resources.
Core Deliverables:
- Technical AI readiness audit & maturity score
- High-ROI use-case feasibility matrix
- Target-state architecture & model selection blueprint
- Inference compute & token cost forecast model
Most Popular 2 to 4 Weeks Dedicated
Architecture & Delivery Sprint
$9,500 / ₹7.5L
Fixed Milestone Investment
In-depth system design, code repository audits, LLM eval benchmark harnesses, or unblocking complex roadmap features.
Core Deliverables:
- Formal Architectural Decision Records (ADRs)
- Hands-on codebase & security vulnerability review
- Evaluation benchmark harness for LLM accuracy/latency
- Sprint-ready backlog with engineering specifications
Ongoing Leadership Monthly Retainer
Strategic Advisory Retainer
$5,000 / month
Or ₹4L / month (Flexible Commitment)
Fractional Head of AI or CTO advisory, continuous architecture reviews, vendor evaluations, and board technical oversight.
Core Deliverables:
- Weekly executive technical strategy sessions
- Asynchronous architecture & PR code review support
- Vendor due-diligence & AI build-vs-buy analysis
- Priority incident and architectural escalation access
LEAD ADVISORY PRACTITIONER
Advisor Profile
Direct strategic leadership from engineers who have shipped autonomous systems to production under stringent enterprise SLAs.
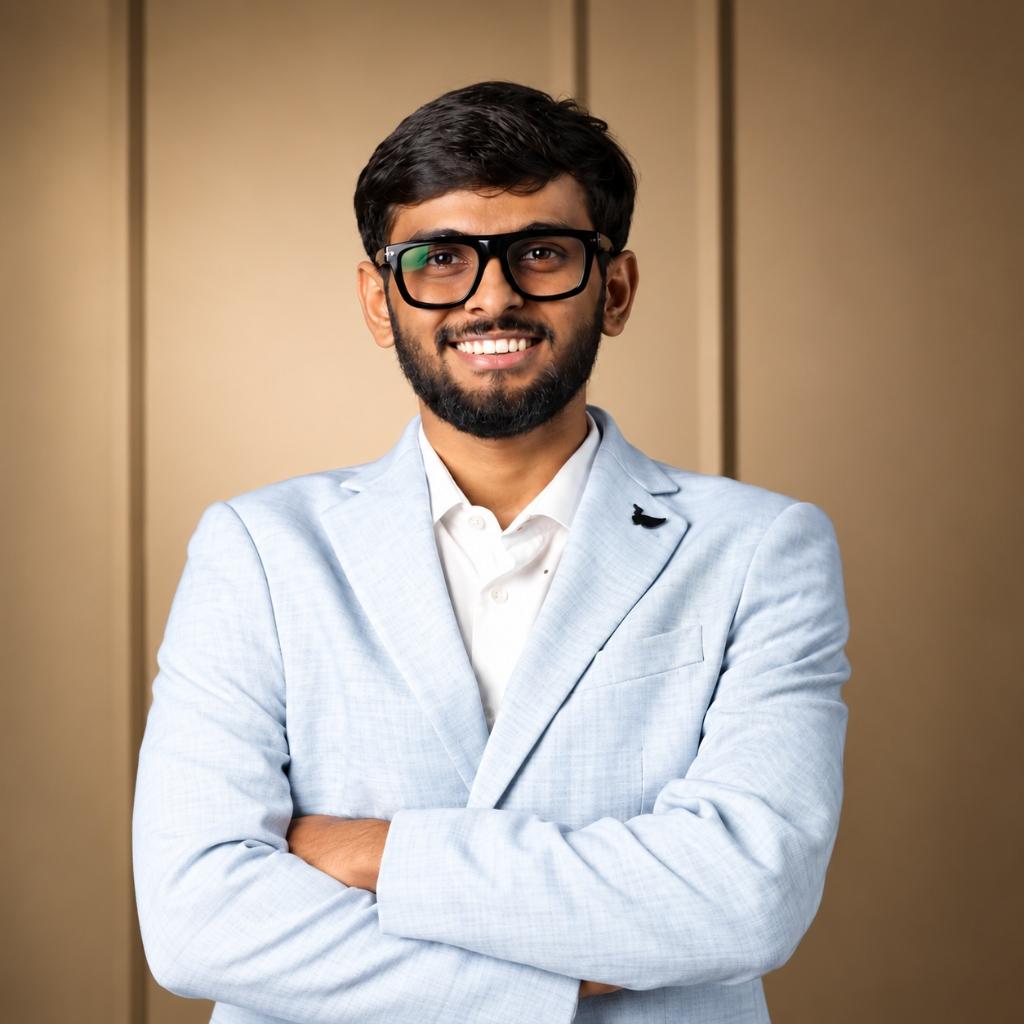
HEAD OF PRACTICE & FOUNDERDPIIT & Startup India Recognized
Tirth Patel
Founder & CEO, Neno Technology · Co-Founder, Gujarat AI Society & Agentic Bharat
Leading enterprise AI strategy, system architecture, and autonomous platform development at Neno Technology. Over a decade of deep technical experience engineering high-scale distributed backends, low-latency telephony infrastructure (<200ms), and multi-agent production swarms.
“We advise from active production codebases, not theoretical slide decks. Every recommendation we give is grounded in architectures we have personally shipped, hardened, and benchmarked under live enterprise traffic.”
Agentic & Multi-Agent Swarms
Real-Time Voice AI Pipelines
SOC 2, Privacy & Guardrails
Token & Compute Optimization